M Ganesh Kumar
I study how humans and machines learn from sparse, delayed feedback and adapt under uncertainty. I build reinforcement learning agents, Bayesian models and theories of learning in deep networks, and test them against human behavior and neural recordings. My goal is a unified theory of learning and adaptation that explains when learning succeeds, why it fails in psychopathology, and how to design AI that learns efficiently and works well with people.
News
- 11/2026Upcoming seminar, Ministry of Education, Singapore: Learning, Memory and Meta-cognition
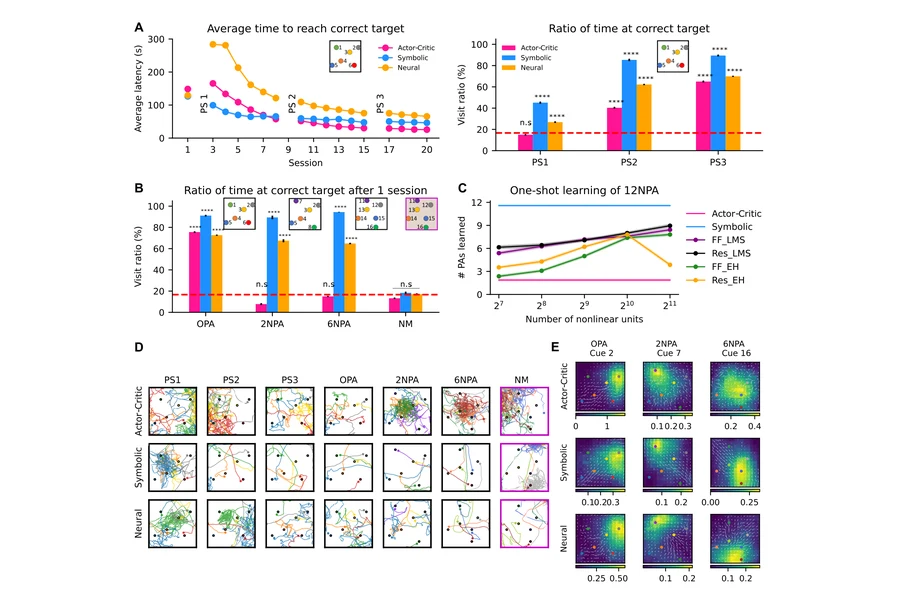
- 10/2026One-shot learning of paired association navigation with biologically plausible schemas published in the Journal of Neuroscience
- 08/2026Keynote at the Tamil Teachers Conference, Ministry of Education, Singapore: Minds, Machines and Mother Tongue
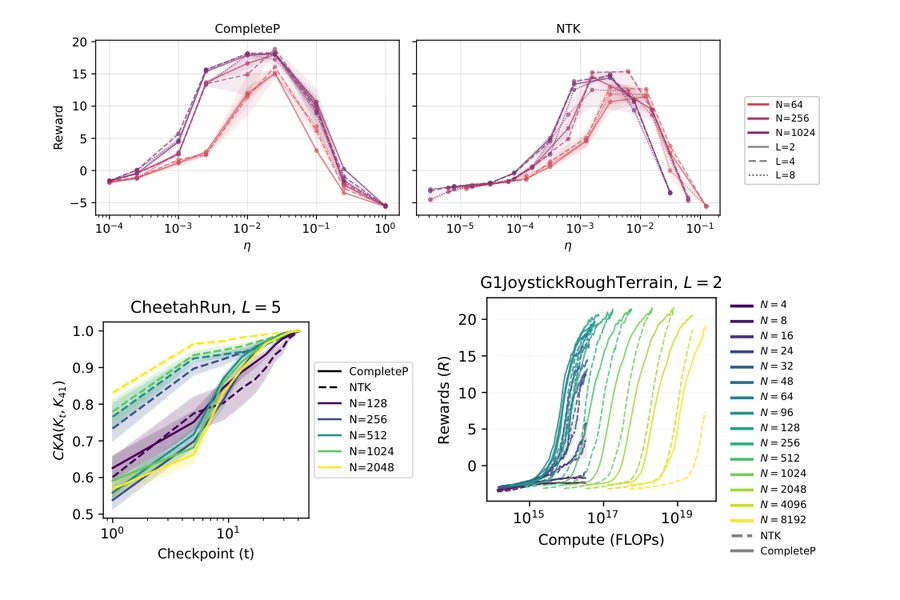
- 07/2026CompleteP for RL at ICML 2026, Seoul
- 02/2026Invited talk, Department of Physiology, National University of Singapore
- 01/2026Joined the Max Planck Institute for Biological Cybernetics as a Research Scientist with Peter Dayan
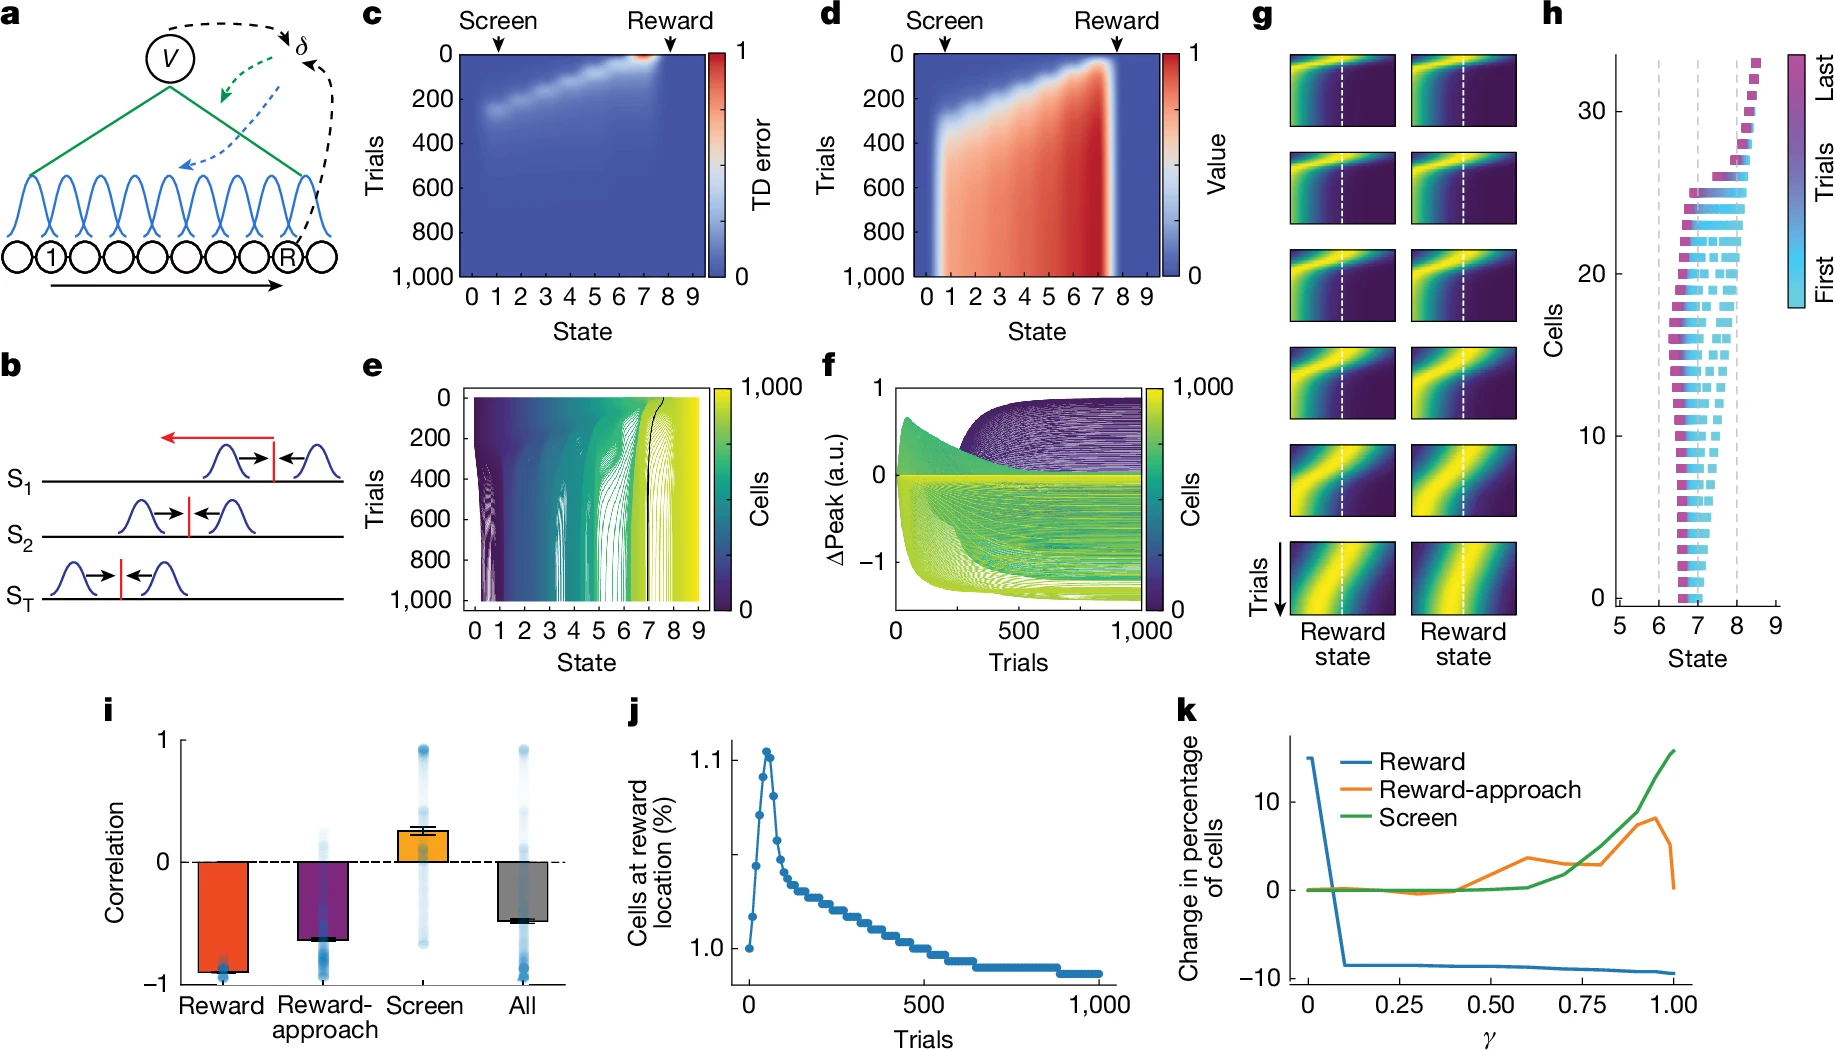
- 01/2026Predictive coding of reward in the hippocampus published in Nature
- 09/2025Invited talk, Institute of Cognitive Neuroscience, University College London
Selected publications
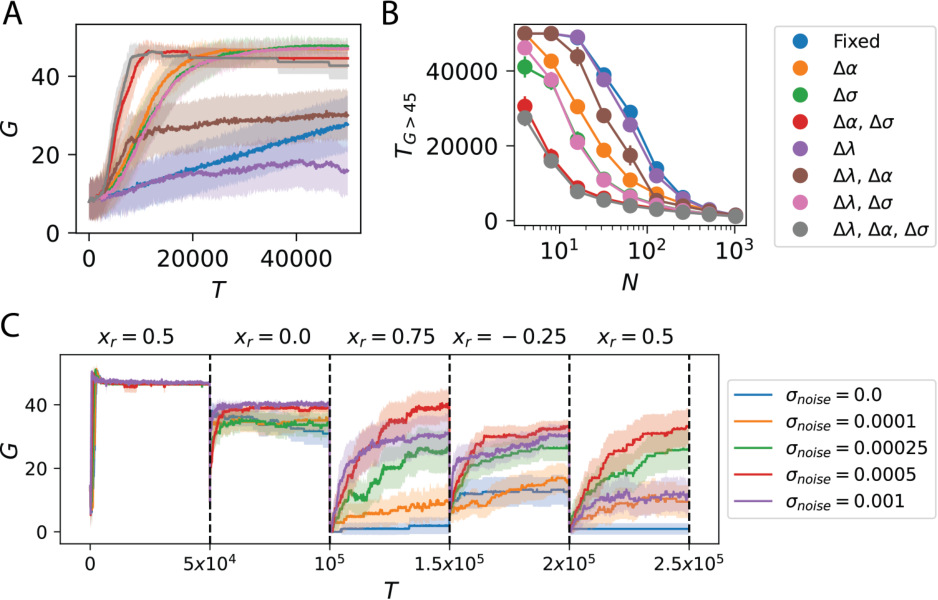
* equal contribution · + I developed the theory and ran all model simulations · All publications →
Research
Humans and artificial agents must infer the hidden causes of their outcomes from sparse, delayed and ambiguous feedback. A student who fails an examination may blame their skill, the difficulty of the test or bad luck, and that explanation shapes what they do next. I study how such inferences are learned, how they go wrong, and how they are implemented, at three levels of analysis.
How do people form beliefs, assign credit and adapt?
Bayesian models of how people attribute success and failure to skill, difficulty and luck. Human experiments relate these biases to depression, anxiety, culture and trust in AI.
What makes learning efficient, and what makes it fail?
Reinforcement learning, feature learning and scaling in deep networks, and interpretable meta-RL agents that can be probed and steered.
How do neural circuits carry out these computations?
Spiking networks with neuromodulated plasticity, and how perturbations such as stress or NMDA receptor hypofunction change learning.
Applications
Publications
* equal contribution · † equal senior contribution · + see contribution note · In machine learning, ICML, NeurIPS, ICLR and ICCV proceedings are selective (<30% acceptance) archival publications.
Manuscripts in preparation
Research articles
Book chapter
Short papers
Students I supervise
Teaching
- 2025Teaching Fellow, APMTH 50: Introduction to Applied Mathematics, Harvard University60 students. Led weekly tutorials of 30 students and supervised group paper presentations and final project proposals.
- 2019Guest Lecturer and Practical Facilitator, LSM4213: Systems Neurobiology, NUSLecture on brain-computer interfaces. Facilitated the electromyography practical for 60 students.
- 2019 – 2020Graduate Research Mentor, Special Programme in Science, NUSSupervised a group project on brain activity in schizophrenia.
- 2019 – 2022Outreach and continuing education, NUSNUS Braincamp (2019), Beginning AI Through Neuroscience (2021), Neuroscience, AI and Medicine Workshop (2021), STEP NUS Braincamp (2022)
Teaching interests: computational models of cognition, brain-inspired AI, reinforcement learning, and computational psychiatry.
Service and leadership
Singapore Armed Forces
I plan operations for a battalion of about 700 National Servicemen. I previously served as a combat engineer platoon and company commander. I hope to apply my research on learning to the resilience and well-being of National Servicemen.
Tamil community
I am leading an initiative to develop a language model with strong Tamil capabilities. I organized the Tamil + AI symposium in 2019, presented AI Singapore's AI for Everyone series in Tamil, and speak to the Ministry of Education on learning, metacognition and AI for Tamil teachers. I have also produced, directed and acted in Tamil theatre.
Industry and innovation
Nugen.ai
Wearables that measure students' physiological states during learning, giving educators and parents feedback on engagement and stress. We funded and mentored an SUTD Capstone team that built the prototypes, and ran a preschool pilot.
Noova Tech
Locally deployed agentic AI systems for data security.
Certified Scrum Product Owner and Certified ScrumMaster.
Outside work
✈️ Pilot
FAA-certified private pilot. Navigating landmarks at 5,000 ft requires 3D place fields.
🏍️ Motorcycle
It forces you to be present and situationally aware, or end up in the mud like I have.
🚗 Road trips
Long drives are good for thinking through hard problems, or for letting system one take over.
🏋️ CrossFit
My wife convinced me it was fun and useful, so that I can run after my son. I believe she is right.
Appointments
- 2026 – presentResearch Scientist, Department of Computational NeuroscienceMax Planck Institute for Biological Cybernetics, Germany · with Peter Dayan
- 2023 – 2025Postdoctoral Fellow, School of Engineering and Applied SciencesHarvard University, United States · with Cengiz Pehlevan
- 2022 – 2023Research Scientist I, Centre for Frontier AI ResearchA*STAR, Singapore
- 2017 – 2018Research Engineer, A*STAR Artificial Intelligence InitiativeA*STAR, Singapore
Education
- 2018 – 2023Ph.D. in Computational Neuroscience, National University of SingaporeAdvisors: Andrew Tan, Shih-Cheng Yen · Thesis committee: Thomas Yeo
- 2013 – 2017B.Sc. (Honours with Distinction) in Life Sciences, National University of SingaporeMinors: University Scholars Programme and Special Programme in Science
Grants, fellowships and awards
- 2025, 2026Young NUS Fellow, NUS Development Grant (SGD 40,000)
- 2025Spotlight talk and Travel Award (EUR 1,000), Computational Psychiatry Conference
- 2025Spotlight poster and Travel Award (USD 500), COSYNE
- 2023Postdoctoral Fellowship in Computer Science, Harvard University
- 2019Fujitsu Laboratories Fellow, MIT Center for Brains, Minds and Machines
- 2018NUS Graduate School Scholarship
- 2017NUSS Gold Medal for Outstanding Achievement
- 2013A*STAR Undergraduate Scholarship
Selected invited talks
- 2026Ministry of Education, Singapore (keynote, Tamil Teachers Conference; workplan seminar)
- 2026Department of Physiology, National University of Singapore
- 2025Institute of Cognitive Neuroscience, University College London
- 2025Kempner Institute, Harvard · LMU–Harvard Young Scientists' Forum, Munich
- 2022McGovern Institute and Department of Brain and Cognitive Sciences, MIT
Service
- ReviewerNature Communications, Neural Networks, PLOS Computational Biology, Frontiers in Systems Neuroscience, IEEE TCDSNeurIPS, ICLR, ICML, CCN, COSYNE
- OrganizingOrganizing Committee, Society for Neuroscience Singapore Chapter
Tamil Open Data Repository
A pilot collection of high-quality, teacher-created Tamil teaching material — built so that future AI systems can actually learn Tamil properly. Every contribution is credited, anonymised, and openly licensed.
Why this matters
First — what is a "token"?
Counting tokens: tokens are occurrences, not distinct words
The same word in Tamil costs about twelve times more
- Type an English sentence. Watch the token count sit close to the word count.
- Now type the same sentence in Tamil. The count jumps several times higher.
- Try a single word —
teacher, thenஆசிரியர். Same meaning, wildly different cost. - Click "Show token IDs" to see the fragments. For Tamil, many will be meaningless slivers rather than letters.
- Switch the tokenizer between GPT-4o and GPT-3.5 & GPT-4 using the selector, and watch the Tamil count drop by roughly two-thirds. Nothing about the Tamil changed — only the dictionary did. That is the whole argument for this repository in one click.
There is a sting in this. Token counts flatter Tamil. The same idea written in Tamil produces more tokens than in English while carrying no more meaning — identical content, chopped finer. Measured in tokens, Tamil looks less far behind than it is. Measured in ideas, the gap is worse than it appears.
The consequence teachers feel without knowing why: at the same context limit, a Tamil user fits about 15% of what an English user fits. Paste a long composition into a chatbot in Tamil and it runs out of memory roughly six times sooner.
Large language models are trained largely on Common Crawl, an open snapshot of the public web. The July 2026 crawl contains about 2.14 billion web pages. Here is how the languages divide it up.
| Language | Share of pages | Est. pages | Est. tokens |
|---|
Percentage figures are Common Crawl's own published statistics for crawl CC-MAIN-2026-30 (July 2026), which identifies the primary language of each page. Page and token counts are estimates derived from the 2.14 billion page total, assuming roughly 1,000 tokens of extracted text per page. Source: Common Crawl language statistics.
The goal: get Tamil to 1%
Around 80 million people speak Tamil, and it is one of the world's oldest living classical languages. Yet it makes up 0.0488% of Common Crawl — while English makes up 40.6%. English has roughly 830 times more presence on the web that AI systems learn from.
To reach 1% of Common Crawl, Tamil needs roughly 20 million more pages of text — about 20 billion additional tokens.
What this repository has collected so far
Token counts are estimates: approximately 1,200 tokens per page of digital text and 600 tokens per page of handwritten or scanned material. They are indicative of scale, not exact measurements.
What we are looking for
The teacher's markings are the point
A clean, unmarked worksheet teaches an AI model very little. What is genuinely rare — and what no web scraper can ever collect — is your judgement made visible: the error identified, the correction supplied, and the reasoning behind it. Please contribute material that carries your input, whether as red ink, margin comments, tracked changes, rubric scores or annotations.
📄 Digital files
- Word documents, PDFs, PowerPoint, plain text, spreadsheets
- Worksheets and comprehension passages with model answers
- Exam or assessment questions paired with correct answers and marking schemes
- Student compositions with tracked changes or inserted comments
- Lesson plans, grammar explanations, vocabulary lists, rubrics
- Anything reflecting Singapore Tamil usage, register, or local context
📷 Handwritten and scanned material
- Photographs or scans of marked student work — red ink corrections are ideal
- Compositions with your annotations in the margins
- Marked answer scripts showing what was wrong and what the correct answer is
- Handwritten model answers and worked examples
- Whiteboard or blackboard explanations you have photographed
Especially valuable
- Question → student answer → teacher's correct answer triples. This is the single most useful format for training and evaluating AI.
- Composition drafts showing the before and after of your feedback.
- Anything involving spoken or colloquial Singapore Tamil, which current AI handles poorly.
- Classical and literary Tamil with commentary — where AI is least reliable today.
Student privacy is mandatory
Remove every student name before you upload
A redaction tool is built into the uploader below. For photographs and scans, you can drag black boxes over any name directly in your browser. The redaction is permanently burned into the image, and the original file never leaves your computer — only the redacted version is uploaded. Camera and location metadata are stripped automatically in the process.
Where a name is part of the pedagogical content — a composition about a person, for instance — replace it with a generic name such as மாறன் or கமலா rather than deleting it, so the sentence still reads naturally.
Teacher access
Sign in or register
Access is limited to Tamil language teachers and educators. Enter your details and we will email you a secure sign-in link — clicking it verifies your address. There is no password to remember.
We store your name, email, role and institution solely to verify contributors and to credit contributions. Your email address is never published.
Questions
Who can see what I upload?
During the pilot, only the project maintainer. Nothing is published automatically. Before any material is released or shared with a partner organisation, contributors will be told what is being released and given the opportunity to withdraw their material.
Will I be credited?
Yes. Your name and institution are recorded with every contribution, and any published dataset will carry a contributor list. If you would prefer to contribute anonymously, say so in the notes field and we will honour it.
Can I withdraw material later?
Yes. Email m.ganeshkumar138@gmail.com and it will be removed. Once a dataset has been publicly released, prior copies cannot be recalled — which is why nothing is released without notifying contributors first.
What licence will the data carry?
The intention is an open licence permitting research and AI development with attribution required — most likely CC BY 4.0. This will be settled in consultation with contributors and any institutional partner before release, not decided unilaterally.
Is this an official MOE project?
No. This is an independent pilot run by Dr M Ganesh Kumar to demonstrate feasibility. If it succeeds, the case for a properly resourced national repository becomes much easier to make.
I have material but I am not a teacher — writers, publishers, historians?
Please get in touch directly. High-quality Tamil prose of any kind is valuable; this pilot is simply scoped to teachers first because classroom material with corrections is the rarest and most useful kind.